Lesson 5 of 7 · 8 min
Layered defence against adversarial AI
The answer to attacks on AI is not a better single model but several independent checks. Learn how behavioural detection, input validation and human review combine so no single failure is fatal.
Security people have a name for defences built as independent layers: defence in depth. The idea is old, but it matters more once machine learning is involved, because models fail in ways that are hard to predict. A model can be excellent on average and still be steered by one carefully prepared input. The goal of a layered design is simple: an attacker who beats one layer should still have to beat the next, and the next, each looking at something different.
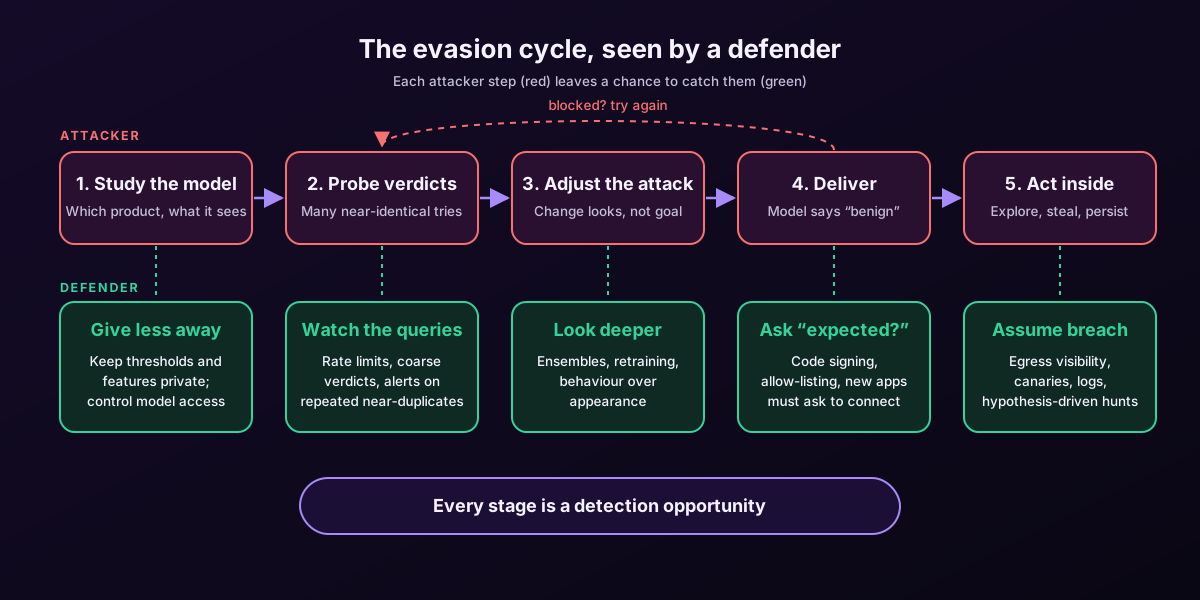
Three kinds of layer that complement ML
| Layer | What it looks at | Why it is hard to fool at the same time as the model |
|---|---|---|
| Behavioural detection | What a program does over time: which files it touches, which processes it starts, where it connects | Behaviour is tied to the attacker’s goal; hiding it means giving up part of the attack |
| Input validation and allow-listing | Whether an input is expected at all: signed by a known developer, in the right format, from an approved source | It rejects the unexpected instead of trying to judge it |
| Human review | Context no model has: who should be doing this, and does it make sense today? | People notice when something is out of place for the organisation, not just for the data |
Behaviour over appearance
An evasion attack changes how something looks. It rarely changes what it has to do. A program that steals data must read it and send it somewhere; ransomware must encrypt; a remote-access tool must keep contacting its operator. Defences that watch these actions, rather than only the shape of a file, force the attacker to change the attack itself, which is far more costly than changing its disguise.
Say no to the unexpected
Allow-listing flips the question. Instead of asking “is this bad?”, it asks “is this something we expect?”. Code signing is a good example: on macOS, Gatekeeper and notarization check that software comes from an identified developer and has not been altered. A decision based on a verified signature does not depend on a model’s opinion of the file at all, so model evasion does not affect it.
Keep a person where it counts
Human review cannot scale to every event, and it should not have to. It belongs where the stakes are high or the automated layers disagree or are unsure. Good tools make this cheap by explaining their reasoning in plain language and making every automated decision easy to review and reverse.
- Route low-confidence or high-impact verdicts to a person instead of deciding silently.
- Make every automated block or allow visible, reversible and attributed to a rule or model.
- Show the facts behind a decision, not just the verdict, so reviewers can spot a model that was fooled.
- Regularly sample “benign” decisions for review, not only alerts.
Where FireAI fits
FireAI applies these layers to a Mac’s network traffic. Rules follow each app’s verified code signature, so a fake app cannot borrow a real one’s permissions. Security modes add hard rules that do not depend on a model: in Paranoid mode, tracking traffic, unsigned apps and every unencrypted port are blocked outright. Autopilot only answers on its own when it is confident, shows a prompt with its suggestion otherwise, explains every decision, and any of its decisions can be undone from Suggestions.
Key takeaways
- Defence in depth means independent layers, each looking at something different.
- Behavioural checks force attackers to change the attack, not just its disguise.
- Allow-listing and code signing reject the unexpected without relying on a model.
- Put humans where stakes are high, and make automated decisions visible and reversible.
Check yourself
1. Why does behavioural detection complement an ML classifier well?
- It is always faster
- Hiding behaviour means changing what the attack does, which is costlier than changing its appearance — Right.
- It never needs updates
- It replaces human review
Evasion changes appearance. Behaviour is tied to the attacker’s goal, so it is much harder to hide at the same time.
2. How does allow-listing differ from classification?
- It asks whether something is expected instead of judging whether it is bad — Right.
- It uses a bigger model
- It only works for email
- It blocks everything
Allow-listing rejects what is not expected, such as unsigned code, without needing a verdict on the input.
3. Where does human review add the most value?
- On every single event
- On high-impact decisions and cases where automated layers are unsure or disagree — Right.
- Only after an attack is over
- Nowhere, automation is enough
People cannot review everything, but they add context exactly where a wrong automated decision would be most costly.
Do it with FireAI
Put this lesson into practice on your own Mac.
- Autopilot: FireAI decides the easy connections for you — Let FireAI clear the easy decisions on its own, and always see why.
- Use Autopilot safely: what it decides, and how to correct it — Turn Autopilot on with a clear view of what it’s doing, and fix anything it gets wrong.
- Investigate a connection — Decide with the facts in front of you, not a vague warning.
- Threat lists (opt-in) — Check your traffic against public threat data without sending it anywhere.
- The World map — See where your data actually goes, not just a hostname you’d have to look up yourself.
- Security modes: Home, Coffee shop, Paranoid, Under attack — Match FireAI’s strictness to where your Mac actually is, in one tap.
Sources
- UK NCSC and partners: Guidelines for secure AI system development
- NIST AI Risk Management Framework
- NIST AI 100-2 E2025: Adversarial Machine Learning taxonomy
- MITRE D3FEND
- CISA: Secure by Design
Put it into practice on your Mac
Try every feature free for 17 days, no card needed.