Ders 12 / 18 · 11 dk
Automating attacks: orchestrators and attacker models
Walk through how PyRIT automates single-turn batches and multi-turn conversations, and how the published PAIR and TAP methods use one model to attack another.
Bu sayfa şimdilik İngilizce.
The last two episodes of the series show PyRIT, the open-source Python Risk Identification Tool for generative AI, doing the work of the earlier episodes. PyRIT’s README describes it as “an open source framework built to empower security professionals and engineers to proactively identify risks in generative AI systems”, under the MIT licence [1]. This lesson follows the two workflows and then the research behind the attacker-model idea.
PyRIT’s building blocks
Episode 8 lists the parts: datasets (jailbreak templates, harm categories and objectives), orchestrators (end-to-end attack workflows), converters (transformations such as translation or base64), targets (text, image, speech or a game endpoint), scoring engines, and a memory layer that records what was sent, when and by whom, with notebooks on top [2]. The project has since moved to Microsoft’s main GitHub organisation and its documentation is versioned, so names in current releases may differ from those in the videos. Read the docs for the version you install.
Single-turn automation
Episode 9 sends a batch of prompts through a prompt-sending orchestrator [3]. The steps are a template for any tool:
- Load a dataset of seed prompts, grouped by harm category, and add it to memory.
- Set a memory label, a name that lets you retrieve this run’s prompts later for analysis.
- Configure the target, with endpoint details read from environment variables kept out of the code.
- Choose a scorer. In the demo, success is defined as the model not refusing, so the refusal score is inverted: no refusal means a harm was found.
- Add converters, which can be stacked, to transform each prompt.
- Run the attack, then export the conversations from memory, by label, as JSON or CSV. The export includes the original and converted prompt, the reply and the scores.
The presenter adds an honest caveat: the score sometimes needs tweaking, depending on what you consider harm. In one example a reply gave a disclaimer and then explained anyway, and the scorer counted it as success because there was no outright refusal [3]. That is the subject of lesson 13.
Multi-turn automation: two models against each other
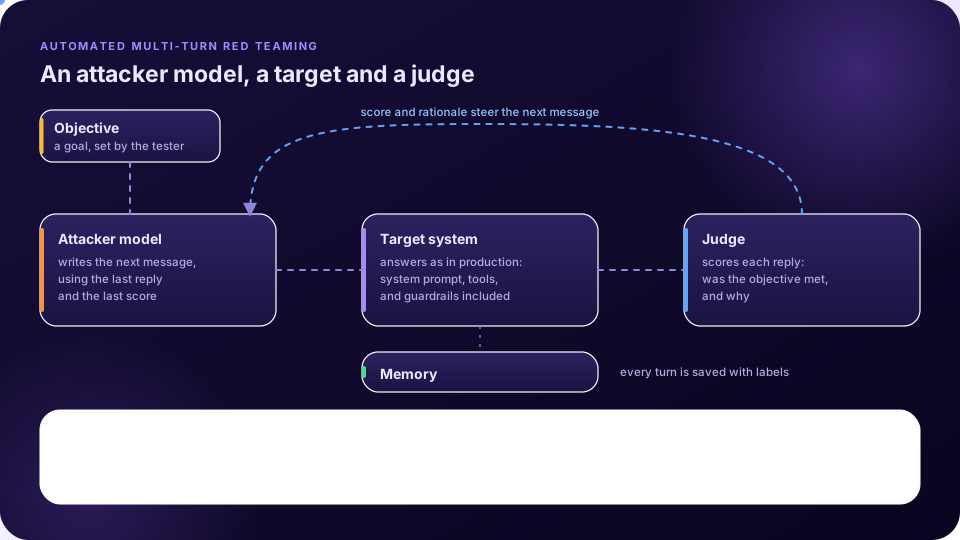
Episode 10 describes the red-teaming orchestrator as pitting two language models against each other. An adversarial chat model is given an objective and a strategy, and writes the prompts. The target answers. A true-or-false scorer decides whether the objective was met. The run has a maximum number of turns and stops early if the objective is achieved. In the demonstration three turns were not enough to succeed, which the presenter notes is expected and adjustable. The same pattern works against other modalities, and the tool retries automatically when a content filter blocks a request [4].
A Crescendo orchestrator automates lesson 6’s technique. It takes a maximum number of turns and a maximum number of backtracks, where a backtrack means the model refused and the attempt rewinds [4].
The research behind the attacker model
- PAIR. Chao and colleagues describe an algorithm, “inspired by social engineering attacks”, that “uses an attacker LLM to automatically generate jailbreaks for a separate targeted LLM without human intervention”, often needing fewer than twenty queries [5].
- TAP. Mehrotra and colleagues’ Tree of Attacks with Pruning has an attacker model iteratively refine candidate prompts, and prune unlikely ones before querying the target. It needs only black-box access to the target [6].
- HarmBench. Mazeika and colleagues note that the field lacked a standardised way to evaluate automated red teaming, and propose a framework; they compare 18 red-teaming methods against 33 target models and defences [7].
Practical cautions
- Cost. An attacker model, a target and a judge are all model calls, and every turn repeats them. Set a turn limit and a budget before you start.
- Reproducibility. Save the attacker’s configuration, the objective, the scorer and the model versions with the results.
- Containment. Attacker-model output is dangerous material by design. Store it with the same care as findings.
- Humans still matter. Automation covers breadth; people choose objectives, check judgments and decide what the results mean.
Akılda kalsın
- PyRIT automates workflows from datasets and converters to orchestrators and scorers, with memory for records.
- A single-turn batch needs a target, a scorer, optional converters and an export.
- The multi-turn loop pairs an attacker model, a target and a judge, with turn limits and stop conditions.
- PAIR and TAP are published attacker-model methods; HarmBench compares such methods in a standard way.
- Budget, record and contain the output of automated runs.
Kendinizi sınayın
1. In the single-turn demo, what counts as a successful attack?
- The model does not refuse — Doğru.
- The model refuses
- The reply is short
- The target is offline
The refusal score is inverted: no refusal means a harm was found, which is why scorers need tuning.
2. What does a backtrack mean in the Crescendo orchestrator?
- The model refused and the attempt rewinds — Doğru.
- A reset of the database
- A new target
- Faster output
It limits how many refusals are tolerated before giving up.
3. What is the attacker model’s job in PAIR?
- Automatically generate jailbreaks for a separate target model — Doğru.
- Judge the target
- Store memory
- Translate prompts only
PAIR uses an attacker LLM to generate and refine prompts without human intervention.
4. Why record model versions and scorer settings?
- Results depend on them and must be reproducible — Doğru.
- To make files larger
- To avoid reports
- To hide failures
Without them, a later run may not be comparable.
FireAI ile uygulayın
Bu dersi kendi Mac’inizde uygulamaya koyun.
- Agent profile: yapay zekâ ajanlarınız için bir yapay zekâ güvenlik duvarı — Mac’inizdeki bir yapay zekâ ajanı yeni bir yere eriştiğinde ya da alışılmadık miktarda veri gönderdiğinde bunu öğrenin ve tek kaydırmayla engelleyin.
- Bir bağlantıyı inceleyin — Belirsiz bir uyarı yerine, önünüzdeki gerçeklerle karar verin.
Kaynaklar
- Microsoft PyRIT (GitHub README)
- Microsoft, AI Red Teaming 101, Episode 8: Automating AI red teaming with PyRIT
- Microsoft, AI Red Teaming 101, Episode 9: Automating single-turn attacks with PyRIT
- Microsoft, AI Red Teaming 101, Episode 10: Automating multi-turn attacks with PyRIT
- Chao et al. (2023), Jailbreaking Black Box Large Language Models in Twenty Queries (PAIR), arXiv:2310.08419
- Mehrotra et al. (2023), Tree of Attacks: Jailbreaking Black-Box LLMs Automatically (TAP), arXiv:2312.02119
- Mazeika et al. (2024), HarmBench, arXiv:2402.04249
Mac’inizde uygulayın
Tüm özellikleri 17 gün ücretsiz deneyin, kart gerekmez.